Skip to content
Software Engineer at Grid Dynamics

Backend Engineer

I am a Software Engineer at Grid Dynamics, currently engaged with Visa — a leading global card network — building Java backend services for merchant management. I care about correct data, clear API contracts, and changes that hold up in production. Before this engagement I spent a year shipping AI hiring systems on FastAPI, LLMs and GCP — that work is still where my proudest numbers live.

Scroll

91%

Faster candidate screening

An autonomous scoring engine evaluates every open hiring ticket in a single pass.

90%

Manual recruiter effort removed

Screening workflows that used to be human-driven now run end to end without intervention.

35+

Production REST APIs

Asynchronous FastAPI services backing structured and semantic data workloads.

80%

Execution risk reduced

Untrusted user code isolated inside Firecracker microVMs rather than shared runtimes.
About

I would rather design the system than just ship the endpoint.

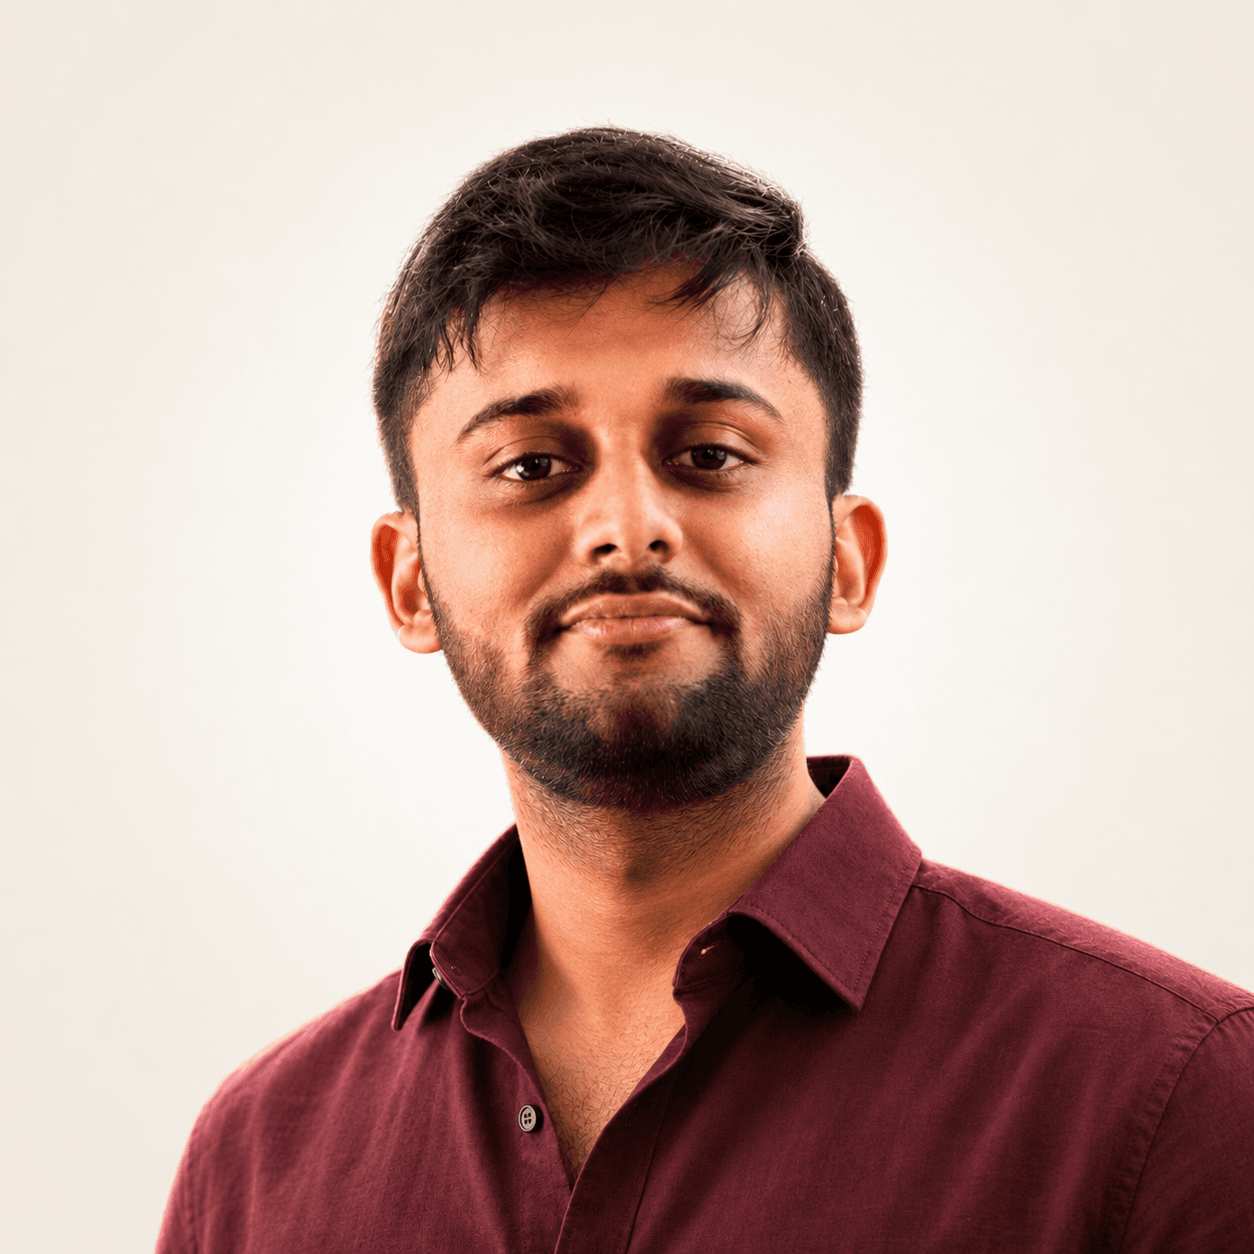
Portrait of Hardik Kumar Singh

Bengaluru, India

Hardik Kumar Singh

IST · UTC+5:30

Impact before novelty

Every architectural choice should be defensible in terms of latency, cost, or hours of human work removed.

Async by default

Blocking a request thread on an LLM call is a design decision. Usually the wrong one.

Isolate what you cannot trust

User code, model output, and third-party responses all get a boundary before they touch the system.

I am Hardik, a Software Engineer at Grid Dynamics in Bengaluru, currently engaged with Visa — a leading global card network — building Java backend services for merchant management. I graduated from MNNIT Allahabad with a B.Tech in Computer Science and Engineering, and I have spent every role since asking the same question: what has to stay true when traffic, data, or team size grows?

On the Visa engagement my work is production Java — merchant workflows, synchronisation with downstream processing, and API contracts that integrators can actually debug. Before that I was on Grid Dynamics' own enterprise AI platforms: asynchronous FastAPI, Vertex AI and GPT-4, PostgreSQL on Cloud Run, and the kind of throughput numbers that only matter if recruiters feel them.

I am not tied to one stack. I go where the problem is — Java and Spring where the enterprise boundary is, Python and FastAPI where models and async I/O dominate. What I optimise for is impact you can measure, whether that is fresher merchant reporting or ninety-one percent less screening time.

Trajectory

  1. 2021

    Started at MNNIT Allahabad

    B.Tech in Computer Science and Engineering, finishing with a CPI of 8.27.

  2. 2024

    Built OptiVision

    Real-time object detection on a Jetson Nano taught me that latency budgets are a hardware conversation.

  3. Jan 2025

    Joined Grid Dynamics as an intern

    Led the backend of an LLM-powered learning assistant and shipped 35+ REST APIs into production.

  4. Aug 2025

    Junior Software Engineer at Grid Dynamics

    Owned backend systems for an AI talent acquisition platform used to automate real hiring workflows.

  5. Sep 2026

    Engaged with Visa, as part of Grid Dynamics

    Still at Grid Dynamics — now building Java backend enhancements across merchant management for Visa, a leading global card network.

Education & credentials

Motilal Nehru National Institute of Technology, Allahabad

B.Tech, Computer Science and Engineering

CPI 8.27

Dec 2021 — May 2025

G.N. National Public School

CBSE, Class XII

95.4%

Apr 2021

AWS Certified Cloud Practitioner

Amazon Web Services

Verify credential
Capabilities

The toolkit, grouped by what it is actually for.

Depth in a handful of things and working literacy in the rest. This is what I reach for, not everything I have installed.

05

Languages

Chosen for the problem, not the résumé.

  • Javaprimary
  • C++primary
  • Python
  • SQL
  • JavaScript
06

Backend & APIs

Asynchronous services that hold their latency budget.

  • FastAPI
  • Spring Bootdeep
  • REST APIs
  • Microservices
  • Async I/O
  • ReactJS
06

Data & Storage

Schemas designed for the queries they will actually see.

  • PostgreSQLdeep
  • JSONB modelling
  • Redis
  • ChromaDB
  • MongoDB
  • MySQL
06

Cloud & DevOps

Containerised, cost-aware, and operable by a small team.

  • Google Cloud Run
  • Cloud SQL
  • Dockerdeep
  • Kubernetes
  • AWS EC2
  • AWS CertifiedCCP
06

AI & LLM Systems

Models treated as a dependency with a latency and cost budget.

  • Google Vertex AI
  • OpenAI GPT-4
  • Semantic search
  • Vector databases
  • TensorFlow
  • OpenCV
07

Tooling & Practice

The unglamorous half of shipping.

  • Git / GitHub
  • GitLab CI
  • Maven
  • JUnit
  • Mockito
  • Agile / Scrum
  • AI assisted tools:Claude, Codex, Gemini, Cursor
Experience

One company, two very different engagements.

Still at Grid Dynamics — currently engaged with Visa on Java merchant platforms. The AI platform numbers below came from the engagement before this one, and every bullet is tied to something that shipped.

Software Engineer · Visa (client engagement)

Grid DynamicsBengaluru, India

Sep 2026 — Present

Engaged by Grid Dynamics with Visa — a leading global card network — engineering Java backend enhancements across merchant management workflows, production defect resolution, and business-driven platform improvements.

  • Engineered Java backend enhancements across merchant management workflows, delivering production features, defect resolutions, and business-driven platform improvements.
  • Resolved a merchant data synchronisation defect by integrating post-onboarding update flows with downstream processing, eliminating stale reporting data through cross-team collaboration.
  • Enhanced API contracts with three validation scenarios, replacing generic HTTP 400 responses with descriptive error enums to improve merchant integration and diagnostics.
  • Proposed and introduced clearer Virtual Terminal terminology, aligning merchant-facing labels with business functionality to reduce ambiguity.
JavaSpring BootREST APIsMicroservicesMavenJUnitVisit

Junior Software Engineer

Grid DynamicsBengaluru, India

Aug 2025 — Sep 2026

Owned backend systems for an AI-powered talent acquisition platform: the APIs, the data model, the model integration, and the deployment path that carried them to production.

  • Built the backend for an AI talent acquisition platform that automates candidate screening, removing 90% of the manual effort recruiters previously spent on first-pass review.
  • Shipped asynchronous, scalable FastAPI services with advanced filtering, pagination and real-time delivery, improving recruiter workflow efficiency by 35%.
  • Integrated Google Vertex AI and OpenAI GPT-4 for CV-to-job-description matching and candidate ranking, raising match accuracy by 35%.
  • Designed an autonomous scoring engine that evaluates a candidate against every relevant hiring ticket in a single pass, cutting screening time by 91%.
  • Replaced profile-keyword evaluation with holistic semantic matching, improving shortlisting consistency by 30% and reducing recruiter bias.
  • Containerised the platform with Docker on Google Cloud Run, cutting operational overhead by 25% while keeping deployments cost-efficient.
  • Modelled cloud-native persistence in Cloud SQL for PostgreSQL using optimised JSONB schemas, improving query performance and data flexibility by 30%.
PythonFastAPIPostgreSQLVertex AIGPT-4DockerCloud RunVisit

Software Engineer Intern

Grid DynamicsHyderabad, India

Jan 2025 — Jul 2025

Led the backend of an LLM-powered learning assistant that turns arbitrary source material — PDFs, repositories, documentation, code — into interactive learning experiences.

  • Led the backend of an LLM-powered learning assistant, converting 90% of supported content types (PDFs, code, docs, GitHub repositories, web links) into interactive material.
  • Engineered 35+ REST APIs in FastAPI over PostgreSQL, ChromaDB and Redis to serve structured and semantic workloads from one interface.
  • Ran untrusted user code inside Firecracker microVMs on Amazon EC2, reducing execution-level security risk by 80% compared with shared-runtime execution.
  • Worked with the data science and frontend teams on chat, Q&A generation and automated code evaluation, lifting learner engagement by 30%.
  • Containerised backend services with Docker, resolving over 60% of outstanding CI/CD pipeline issues and making staging consistent with production.
PythonFastAPIPostgreSQLChromaDBRedisFirecrackerAWS EC2Visit
Selected work

Three systems, and the decisions behind them.

talent-ai.topologyIn production
Recruiter Portal
FastAPI Service
CV Parser
Scoring Engine
Vertex AI
GPT-4
Cloud SQL
Cloud Run
p99 latency · 24h

91%

Faster screening

90%

Manual effort removed

+35%

Match accuracy

-25%

Operational overhead

01 / 032025

AI Talent Acquisition Platform

Screening that finishes before the recruiter opens the tab.

An enterprise platform that automates candidate screening end to end. Every incoming CV is parsed, embedded, semantically matched against open job descriptions, scored, and ranked — without a recruiter having to open a single profile first.

Scoring every ticket in one pass
Evaluating a candidate against one requisition at a time does not scale with the number of open roles. The scoring engine fans a single parsed CV across every relevant hiring ticket concurrently, which is what turned screening time into a 91% reduction rather than a marginal one.
Keeping LLM calls off the request path
Model latency is measured in seconds and request budgets in milliseconds. Matching and ranking run as asynchronous work with results persisted on completion, so the API stays responsive regardless of how long inference takes.
Structure and flexibility in the same schema
Parsed CVs vary wildly in shape. Modelling them as optimised JSONB in Cloud SQL kept relational guarantees for the fields that matter while leaving the long tail queryable, improving query performance and flexibility by 30%.
FastAPIPythonPostgreSQLVertex AIGPT-4DockerCloud Run
Backend owner · Grid Dynamics
learning-assistant.topologyShipped
Sources
Ingestion
FastAPI
ChromaDB
PostgreSQL
Redis
Firecracker microVM
Amazon EC2
p99 latency · 24h

35+

REST APIs shipped

90%

Content types supported

-80%

Code execution risk

+30%

Learner engagement

02 / 032025

LLM-Powered Learning Assistant

Any source material, turned into something you can practise against.

A learning platform that ingests PDFs, GitHub repositories, documentation and raw code, then generates interactive material from them: Q&A, guided explanation, and coding exercises that are evaluated automatically by executing the learner's submission.

Executing untrusted code safely
Learner submissions are arbitrary code. Each execution is isolated in a Firecracker microVM on EC2 with its own kernel and lifetime, which reduced execution-level security risk by 80% relative to running submissions in a shared container runtime.
One API over three storage models
PostgreSQL holds relational state, ChromaDB holds embeddings, and Redis absorbs hot reads. 35+ REST endpoints present all three as a single coherent interface so the client never has to know which store answered.
Ingesting genuinely heterogeneous sources
A GitHub repository, a PDF and a documentation site have nothing structurally in common. A normalising ingestion layer reduced them to a shared chunked representation, which is what made 90% content coverage achievable.
FastAPIPostgreSQLChromaDBRedisFirecrackerDockerAWS EC2
optivision.topologyOpen source
IP Cameras
Stream Decoder
CenterNet R-101
Multi-Object Tracker
Detection Log
Log Chatbot
p99 latency · 24h

34ms

Inference latency

32.4

mAP on CenterNet

5+

Concurrent RTSP streams

85%+

Tracking accuracy

03 / 032024

OptiVision

Real-time detection on hardware that fits in your hand.

A computer vision system for real-time object detection and intelligent surveillance, running CenterNet ResNet-101 on a Jetson Nano across multiple live RTSP streams, with a chatbot layer that answers questions about what the cameras actually saw.

A latency budget set by the hardware
CenterNet ResNet-101 had to hold 34ms inference at 32.4 mAP on a Jetson Nano. The accuracy-per-millisecond tradeoff was the whole design, and it was decided by what the device could sustain rather than what the model could score.
Multiple live streams, one device
Five or more concurrent RTSP streams share a single accelerator. Frame scheduling and tracking state per stream kept multi-object tracking above 85% accuracy without any one camera starving the others.
Making the logs answerable
Ten thousand detection records are a data problem, not an insight. A TF-IDF and cosine-similarity chatbot over the logs let a human ask what happened instead of writing a query.
PythonTensorFlowOpenCVJetson NanoTF-IDF
Solo build · final-year project
Product demo · LLM-Powered Learning Assistant

LLM-Powered Learning Assistant, in motion.

A short walkthrough of the assistant turning raw source material into something you can actually practise against — the same build referenced in the projects above.

Backend lead · Grid Dynamics · 2025
Direct linkView source →
Technical expertise

Five areas, and what I actually mean by them.

Labels are cheap. Each card opens onto the specific practices behind it.

Async as the default

FastAPI services built non-blocking from the start, so an API that depends on multi-second inference still answers in milliseconds and reports progress rather than holding a connection open.

Query-shaped APIs

Advanced filtering and pagination designed against the access patterns the client actually has, which is what turned into a 35% improvement in recruiter workflow efficiency.

Interfaces over implementations

35+ endpoints presenting relational, vector and cache storage as one coherent surface, so callers never need to know which store answered them.

FastAPISpring BootRESTMicroservicesAsync I/O
Contact

I am at Grid Dynamics, currently engaged with Visa on merchant platforms, and still enjoy talking backend design, Java services, and the AI systems work I did before. If you want to compare notes or explore something together, reach out.

Usually replies within a day